Chunkr
Transforms complex documents into structured chunks for RAG and LLM applications
Chunkr is an open source document intelligence API developed by Lumina AI for parsing complex documents into structured data suitable for RAG and LLM applications. It supports inputs like PDFs, DOCX, PPT, Excel, PNG, and JPEG, processing them through layout analysis, OCR, and intelligent chunking to produce outputs in HTML, Markdown, JSON, or plain text. The tool uses vision language models for accurate segmentation and includes features such as bounding boxes for precise element mapping and citation tracking for traceability.
Key functionalities include adaptive chunking strategies that range from fixed size splits to semantic grouping based on content meaning. Users configure pipelines via YAML files, selecting models like GPT 4o or local options such as Ollama. The API operates on a task based system, where uploads return task IDs for polling results, ensuring asynchronous handling of large files. Integration occurs through a Python SDK that supports both synchronous and asynchronous calls, with environment variables for API keys and endpoints.
In comparisons, Chunkr outperforms basic LlamaIndex parsers in handling visual elements and multi page structures, though it requires more configuration. Against Unstructured.io, it provides superior modularity for custom VLM processing but may demand additional setup for non developers. Azure Document Intelligence serves as a cloud alternative with similar OCR capabilities, yet Chunkr offers open source flexibility and lower entry barriers via its free tier.
User feedback highlights high accuracy in text extraction for printed materials, with processing times around two minutes for 50 page documents. Limitations appear in handwriting recognition, where outputs default to images, and complex tables with shading may not fully parse as structured data. The enterprise edition supports on premises deployment for regulated sectors, maintaining auditability through preserved metadata.
For implementation, begin with the Docker quickstart to test local processing, then migrate to cloud API for production scale. Focus on tuning chunk overlap to 20 percent for better context retention in retrieval tasks, ensuring outputs align with downstream embedding models.
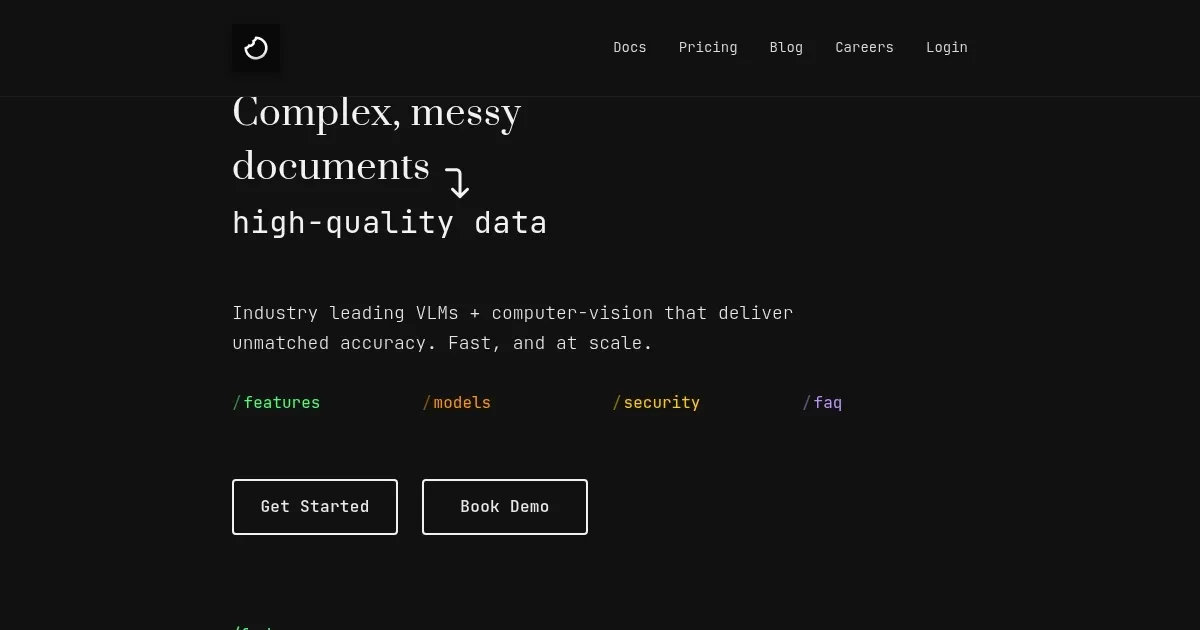
Homepage Screenshot 📸
Video Overview 🎬
What are the key features? ✨
- Layout Analysis: Identifies structural elements like headings and tables for logical segmentation.
- OCR with Bounding Boxes: Extracts text from images and maps positions for precise referencing.
- Semantic Chunking: Groups content by meaning to preserve context in RAG pipelines.
- Multi Format Output: Delivers results in HTML, Markdown, JSON, or text for flexible integration.
- Model Configuration: Allows swapping LLMs like GPT or Ollama for customized processing.
Who is it for? 🤔
Examples of what you can use it for 💡
- RAG Developer: Processes scientific PDFs into semantic chunks for improved query retrieval accuracy.
- Legal Analyst: Extracts clauses and citations from contracts to automate compliance reviews.
- Finance Specialist: Parses invoices and reports into JSON for streamlined data entry workflows.
- Researcher: Converts presentations and images to Markdown for building searchable knowledge bases.
- AI Engineer: Integrates with local LLMs to chunk enterprise docs for custom agent training.
Pros & Cons ⚖️
- High parsing accuracy
- Modular and flexible
- Fast processing speed
- Open source option
- Weak on handwriting
- Config learning curve
FAQs 💬
Ready to try Chunkr?
Transforms complex documents into structured chunks for RAG and LLM applications
Visit ChunkrChunkr alternatives 🔗